Project README
Project quick start, documentation entry points, checks, and citation.
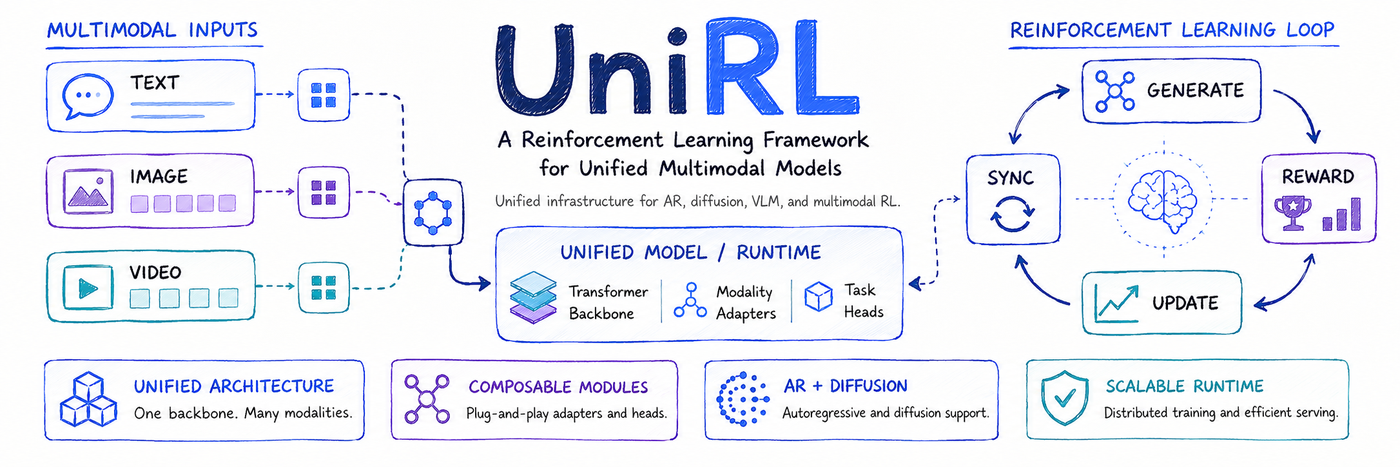
A Reinforcement Learning Framework for Unified Multimodal Models
U(you)·ni(need)·RL for unified multimodal intelligence


News 🚀
- [2026-10] UniRL v0.2.0 released — 12 new model packages, SFT / agentic / async training modes, and SGLang 0.5.19 + vLLM-Omni 0.28 rollout stacks (release notes).
- [2026-06] DRPO released — "Rethinking the Divergence Regularization in LLM RL" (arXiv).
- [2026-06] Flow-DPPO released — "FlowDPPO: Divergence Proximal Policy Optimization for Flow Matching Models" (arXiv).
- [2026-06] CPPO released — "Beyond Uniform Token-Level Trust Region in LLM Reinforcement Learning" (arXiv).
About 💡
UniRL applies one RL post-training loop — generate samples, score them, compute advantages, update the policy, and sync weights back to rollout workers — across multimodal model families.
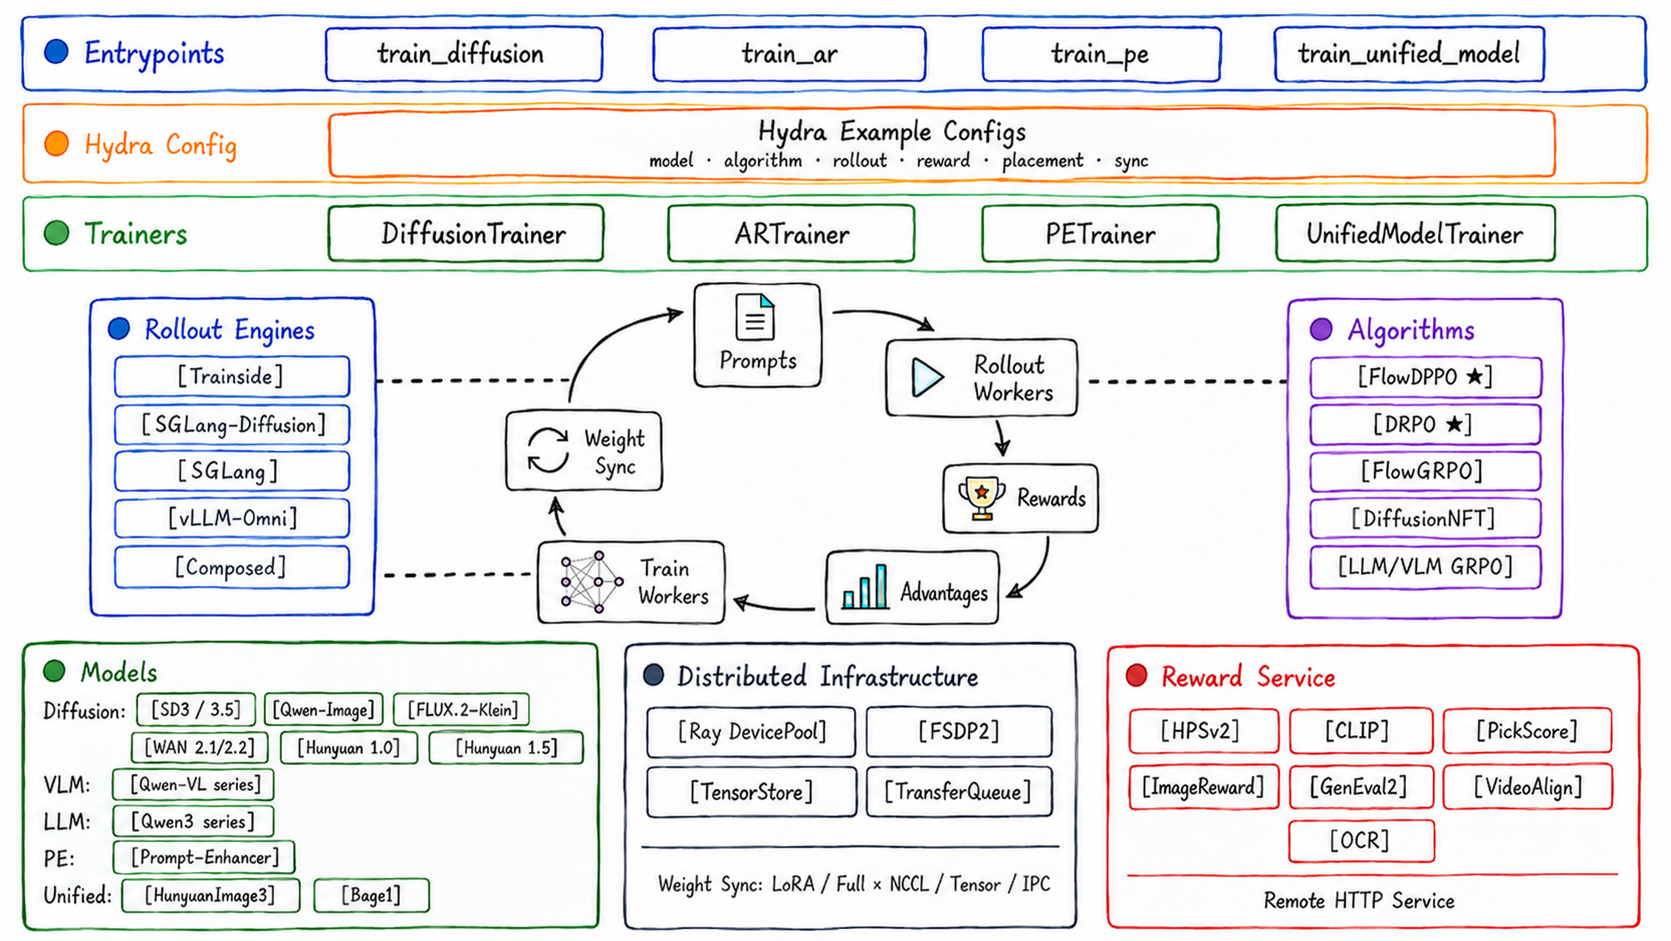
UniRL is a layered, composable system. Each training entrypoint loads a
Hydra example config and creates the matching domain trainer. RL trainers
coordinate generation, scoring, and updates across pluggable
rollout engines, algorithms, model bundles, reward services, and
the shared distributed runtime: Ray DevicePool, FSDP, Transfer
Queue (TQ), and LoRA/full-weight sync. SFT consumes supervised manifests, while
the async AR and diffusion entrypoints overlap rollout with training on separate
GPU slabs. See examples/README.md
for all entrypoints and unirl/README.md for the runtime loop,
deployment modes, and module map.
Team-Proposed Algorithms 🌟
🌟 These algorithms are proposed by our team — the highlight of UniRL. Each algorithm's folder holds a step-by-step tutorial and a runnable example recipe. We highly recommend trying them in our framework!
| Algorithm | Paper | Tutorial | Notes |
|---|---|---|---|
| Flow-DPPO | "Flow-DPPO: Divergence Proximal Policy Optimization for Flow Matching Models" | FlowDPPO/ | Diffusion/flow RL with an exact divergence-based trust-region mask. |
| DRPO | "Rethinking the Divergence Regularization in LLM RL" | DRPO/ | Token-level LLM RL with a smooth advantage-weighted quadratic regularizer. |
| CPPO | "Beyond Uniform Token-Level Trust Region in LLM Reinforcement Learning" | CPPO/ | Token-level LLM RL with a position-weighted, cumulative-prefix-budget Binary-TV mask. |
UniRL also wires in standard reference algorithms — (LLM's)GRPO, DiffusionNFT,
DanceGRPO, and MixGRPO — in unirl/algorithms/.
Model Support 🎨
Model and algorithm support are two independent dimensions that compose within
a domain: any diffusion algorithm (see above) runs on a diffusion
model, AR algorithms on AR models — so UniRL covers many more model × algorithm
combinations than the shipped example recipes alone. The table below is the model
dimension: each row links one runnable recipe. Full matrix — package, every recipe,
rollout engine, and restriction per model — in
unirl/models/README.md.
| Model | Category | Modality | Recipe | Status |
|---|---|---|---|---|
| Stable Diffusion 3.5 | Image diffusion | Text → Image | sd3_trainside | ✅ |
| Qwen-Image | Image diffusion | Text → Image | qwen_image_trainside | ✅ |
| Qwen-Image-Edit-2511 | Image diffusion | Text + Image → Image | qwen_image_edit_plus_nft | ✅ |
| FLUX.2-Klein (4B / 9B) | Image diffusion | Text → Image / Text + Image → Image | flux2_klein_trainside | ✅ |
| Z-Image | Image diffusion | Text → Image | z_image_trainside | ✅ |
| Boogu-Image-0.1 | Image diffusion | Text → Image | boogu_image_trainside | ✅ trainside only |
| WAN 2.1 | Video diffusion | Text / Image → Video | wan21_t2v | ✅ |
| WAN 2.2 (A14B) | Video diffusion | Text / Image → Video | wan22_t2v_14b | ✅ |
| WAN 2.2 V2V | Video diffusion | Video → Video | wan22_v2v_14b | ✅ trainside only |
| HunyuanVideo 1.0 | Video diffusion | Text → Video | hunyuan_video10_t2v_trainside | ✅ |
| HunyuanVideo 1.5 | Video diffusion | Text → Video | hunyuan_video15_t2v_dancegrpo_trainside | ✅ |
| LTX-2 | Video diffusion | Text → Video | ltx2_t2v_trainside | ✅ |
| LTX-2.3 | Video diffusion | Text → Audio + Video | ltx2_3_t2av_trainside | ✅ trainside only |
| MiniMax-H3 | Video diffusion | Text → Video + Audio | minimax_h3_t2va_trainside | ✅ trainside only |
| HunyuanImage 3.0 | Unified AR + diffusion | Text / Text + Image → Image | hi3_trainside_t2i | ✅ |
| BAGEL-7B-MoT | Unified AR + diffusion | Text / Text + Image → Image; Text + Image → Text | bagel_trainside_lora | ✅ |
| SenseNova-U1.5 | Unified MoT pixel flow | Text → Image | sensenova_u1_5_trainside | ✅ trainside only |
| Janus-Pro | Unified AR | Text → Image; Text + Image → Text | janus_pro_grpo_t2i_lora | ✅ trainside only |
| Qwen3 | LLM AR | Text → Text | qwen3_grpo_4b_base_dapo_sglang | ✅ |
| Qwen3-MoE (VeOmni EP) | LLM AR | Text → Text | qwen3_moe_grpo_30b_a3b_veomni_ep_sglang | 🧩 bundle-only |
| Qwen3.5 (9B / 35B-A3B) | VLM AR | Text / Text + Image → Text | qwen3_5_grpo_9b_base_dapo_sglang | ✅ sglang only |
| Qwen2.5-VL | VLM AR | Text + Image → Text | qwen_vl_grpo_geo3k_mc_4x8 | ✅ |
| Qwen3-Omni Thinker | Omni-modality AR | Text / Image / Audio / Video → Text | qwen3_omni_video_r1_gspo_lora_vllm_omni_1x4 | ✅ vllm_omni only |
| Cosmos3-Nano | World model | Video (+ action) prediction | sft/cosmos3_droid100_videopred | 🧪 SFT-only |
| Prompt-Enhancer | LLM + diffusion (composed) | Text → Text → Image | pe_trainside_pickscore | 🔗 composed |
✅ runnable end-to-end with the linked recipe (a qualifier names the only rollout engine that has a recipe) · 🧩 bundle-only (no pipeline of its own; runs under another package's pipeline) · 🧪 SFT-only (no rollout path) · 🔗 composed from other rows. SFT, async, agentic, and scorer-service requirements per model are in the full matrix.
Training Modes 🧩
Each entrypoint has one built-in default, used when --config-name is omitted.
| Training path | Trains | Entrypoint | Built-in default recipe |
|---|---|---|---|
| Diffusion RL | Image / video diffusion models | train_diffusion | diffusion/sd3/sd3_trainside |
| AR RL | Vision-language (VLM) + text-only (LLM) models | train_ar | ar/qwen_vl_grpo_geo3k_mc_4x8 |
| SFT | Supervised text, multimodal, and diffusion models | train_sft | sft/qwen3_sft |
| Prompt enhancement | AR rewriter + diffusion reward | train_pe | pe/pe_trainside_pickscore |
| Unified RL | Unified AR + diffusion models | train_unified_model | unified_model/hi3_vllmomni |
| Agentic RL | Service-scored multi-turn tool use | train_agentic | deep_research/deep_research_search_judge |
| Async AR RL | AR models with separate train / rollout workers | train_async_ar | ar/qwen3_grpo_4b_base_dapo_sglang_async |
| Async diffusion RL | Diffusion models with separate train / rollout workers | train_async_diffusion | diffusion/bagel/bagel_vllmomni_async |
See examples/README.md for the full launch guide, naming
schema, and how to add a recipe.
Agentic Workflows 🤖
train_agentic extends the AR path with multi-turn tool use. Each turn is a
Sample in a lineage; terminal answers are scored by a reward service, and
training waits at a colocated rollout barrier.
AgenticTrainer synchronizes current training weights before every rollout,
dispatches sibling trajectories concurrently, and waits for complete GRPO groups
before scoring and training. Each successful trajectory receives one group-normalized
advantage, which is applied to every generated assistant turn. Failed
trajectories are excluded from the update.
See the agent environment guide for the environment, tool, and trajectory contracts.
Getting Started ⚡
Install dependencies first — see INSTALL.md.
# compose-check, then launch a single-node example
python -m unirl.train_diffusion --config-name=diffusion/sd3/sd3_trainside --cfg job --resolve
bash examples/run_experiment_single_node.sh diffusion/sd3/sd3_trainside
Full launch guide — multi-node, every entrypoint, mooncake.
Roadmap 🗺️
We are actively expanding model and algorithm coverage. Near-term directions:
- Broaden algorithm coverage for the newer model families — FLUX.2-Klein, HunyuanVideo 1.0 / 1.5, and Bagel.
- Extend the team-proposed algorithms (Flow-DPPO, DRPO) to more model families.
- Broaden reward backends and rollout-engine coverage across domains.
Want a model or algorithm prioritized? Open a feature request to discuss.
Contributing 🤝
Contributions and questions are welcome. Before opening a pull request, read the
repository conventions in AGENTS.md, run the
pre-PR checks for the files you
touched, and fill in the pull request template.
Use the issue forms for a
bug report
or
feature request.
WeChat is fine for chat; bugs still belong on GitHub so they stay searchable.
Acknowledgement 🙏
UniRL builds on ideas and infrastructure from the open-source RL and inference ecosystem. We especially thank vLLM, SGLang, slime, and verl.
Citation 📚
If you find UniRL helpful, please cite:
@misc{unirl_github,
  title        = {{UniRL: A Reinforcement Learning Framework for Unified Multimodal Models}},
  author       = {Haonan Wang and Linyu Wu and Qian Qiu and Lewei Jin and Bowen Ping and Jianghai Chen and Yiheng Du and Guangxin He and Yu Shi and Yongguang Lin and Zhuoxin Zhou and Zhanchao Zhou and Keming Wu and Rizhen Hu and Xuefei Ning and Lvfang Tao and Feiyu Hu and Xiangyan Liu and Siqi Kou and Jiarui Yao and Xiangxin Zhou and Liefeng Bo and Wenxi Zhu and Tianyu Pang},
  year         = {2026},
  howpublished = {\url{https://github.com/Tencent-Hunyuan/UniRL}},
  urldate      = {2026-06-05}
}
If you use DRPO, please also cite:
@article{yao2026rethinking,
  title={Rethinking the Divergence Regularization in LLM RL},
  author={Yao, Jiarui and Zhou, Xiangxin and Qi, Penghui and Lee, Wee Sun and Bo, Liefeng and Pang, Tianyu},
  journal={arXiv preprint arXiv:2606.09821},
  year={2026}
}
If you use Flow-DPPO, please also cite:
@article{ping2026flow,
  title={Flow-DPPO: Divergence Proximal Policy Optimization for Flow Matching Models},
  author={Ping, Bowen and Zhou, Xiangxin and Qi, Penghui and Luo, Minnan and Bo, Liefeng and Pang, Tianyu},
  journal={arXiv preprint arXiv:2606.11025},
  year={2026}
}
Source:
README.md— edit the README next to the code, then runnpm run sync:readmesfromdocs/.