Algorithms
Train-side loss algorithm contracts and the reward-to-gradient path.
Where it fits: the loss half of the train step — rollout → reward → advantage → train → sync. In: a track with advantages (supervised / teacher-anchored algorithms opt out via
requires_advantages = False). Out: gradients on the model (the optimizer step in../trainconsumes them). Full map:../README.md.
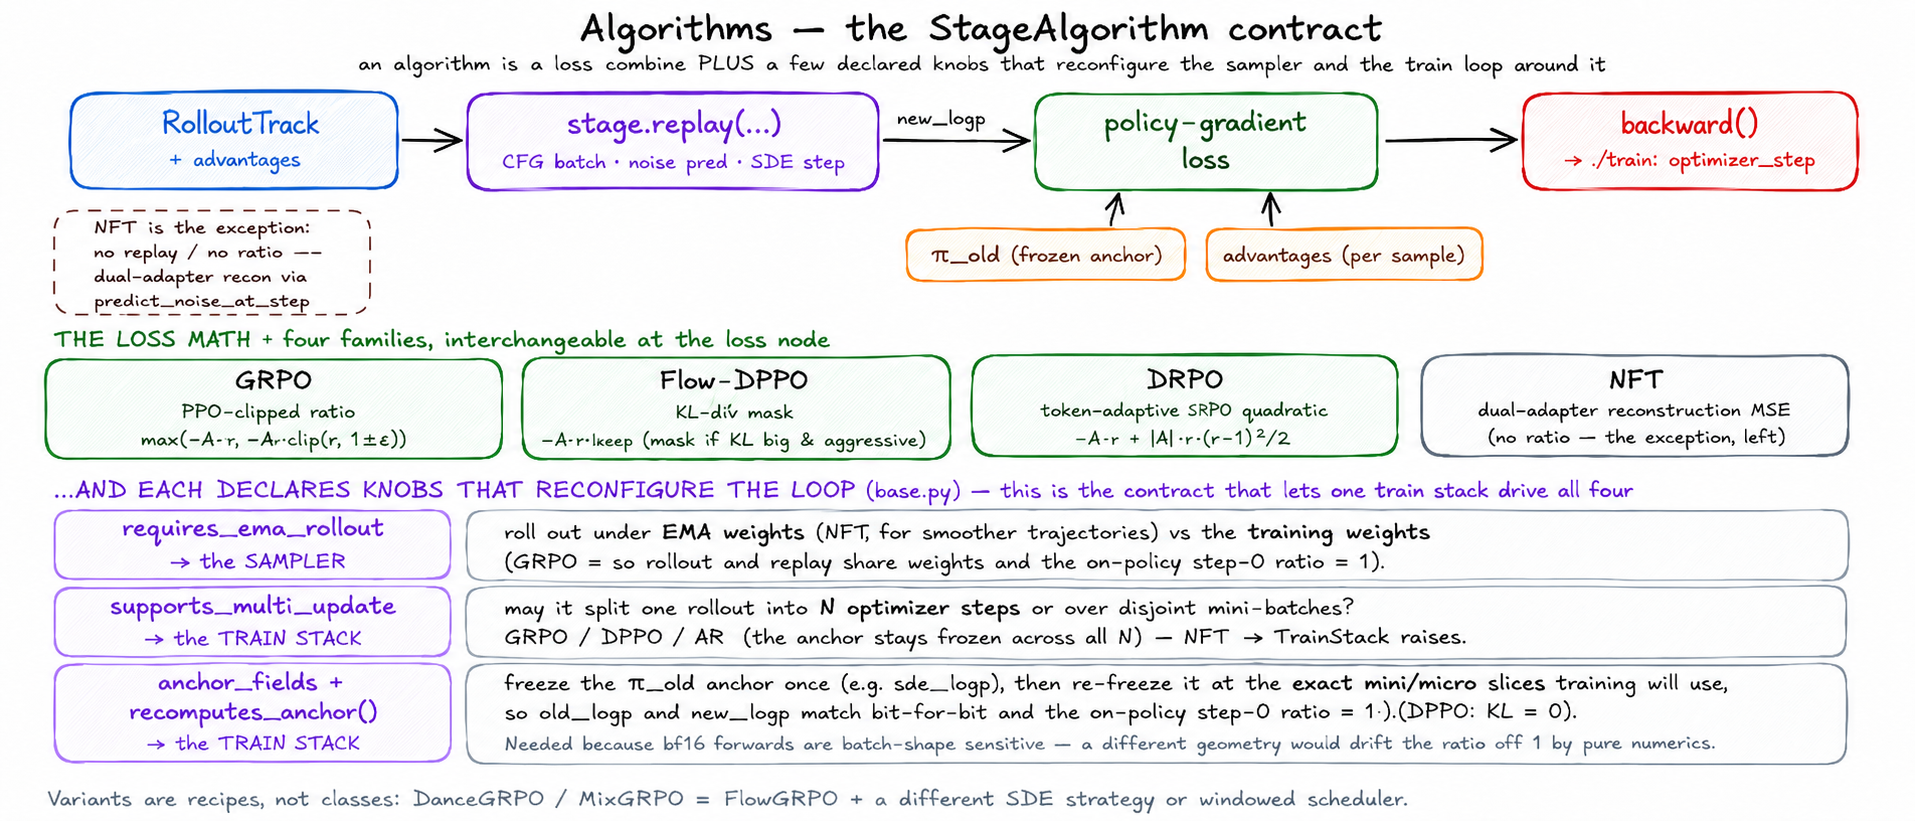
A StageAlgorithm is two things: a loss combine (stage.replay → new_logp, mixed with the frozen π_old anchor and advantages — four interchangeable families) and a few declared knobs (requires_ema_rollout, supports_multi_update, anchor_fields/recomputes_anchor) that reconfigure the sampler and the train loop around it.
What it is
unirl.algorithms is the train-side loss half of the framework. Each algorithm is
a StageAlgorithm that takes a rollout track with advantages already attached,
replays the stage at the current weights, computes a policy-gradient loss, and
calls backward(). It owns the loss math and nothing else — no optimizer, no
model, no data.
Why it exists
The four objectives need different things from the rest of the train step, and
StageAlgorithm is where that divergence is declared without forking the trainer.
Two class attributes drive the surrounding machinery: requires_ema_rollout tells
the sampler whether to roll out under EMA weights (DiffusionNFT sets it True; GRPO keeps it
False so rollout and replay share weights and the step-1 ratio is exactly 1), and
supports_multi_update tells TrainStack whether one rollout may be split into N
optimizer steps (it raises if a False algorithm meets num_updates_per_batch > 1).
The π_old anchor geometry is not centralized here — the algorithm only declares
anchor_fields / recomputes_anchor; TrainStack does the per-slice recompute.
So this module keeps four rollout/update contracts selectable at the loss node,
not just three-tensor arithmetic.
How it works
- The loop. The trainer builds one algorithm per track and hands it to a
TrainStack. Per rollout the stack runsprepare_segmentonce (freeze the π_old anchor), thennum_updates_per_batchoptimizer steps over disjoint mini-batches, each a micro-batch loop ofcompute_loss_and_backward. compute_loss_and_backwardis pure ratio/quadratic math. It delegates the whole forward — CFG batching, noise prediction, SDE stepping — tostage.replay(...)and gets backnew_logp(DiffusionNFT is the exception: it runs its own dual-adapter loop viapredict_noise_at_step). The families: GRPO is a PPO-clipped ratio (flowgrpo.py/grpo.py); FlowDPPO masks-A·rby a Gaussian-KL-vs-advantage criterion (flowdppo.py); DiffusionNFT is a dual-adapter reconstruction MSE (diffusionnft.py); DRPO is a token-adaptive SPO quadratic (drpo.py); DiffusionOPD is the teacher-anchored family — a per-step Gaussian KL against frozen teacher LoRA adapters (backend-ownedfrozen_adapters), distillation rather than RL: it ignores advantages and picks its teacher from the batch'smetadata["domain"](diffusionopd.py).- The anchor contract — the subtle part. bf16 forwards are batch-shape
sensitive, so a π_old anchor computed at a different geometry than
new_logpdrifts the on-policy ratio off 1 (and FlowDPPO's KL off 0). Algorithms just declareanchor_fields(which segment fields to freeze) andrecomputes_anchor(whetherprepare_segmentreplays);TrainStackthen recomputes the anchor over the exact same mini/micro slices it will train on. No hardcoded field names. - Variants are recipes, not classes. DanceGRPO and MixGRPO are
FlowGRPOwith a different SDE strategy or a windowed index scheduler. Add a class only when the loss math itself changes.
Extending it: a new diffusion loss subclasses StageAlgorithm, calls
stage.replay(...), computes a per-element loss, and (loss * loss_scale).backward();
if it needs multi-update, set anchor_fields and supports_multi_update = True and
declare recomputes_anchor when prepare_segment must follow the planned micro
geometry (see FlowGRPO). A new AR loss mirrors GRPO (early-return on an empty
segment, expand advantages per token), keeping supports_multi_update = False.
Gotchas
old_logp_source: rolloutwith a replay-only engine — a separate-worker SGLang rollout emits no per-stepsde_logp, so therolloutsource raises inprepare_segment. Usereplay(the cost is one extratorch.no_gradreplay).num_updates_per_batch > 1on DiffusionNFT raises inTrainStack.__init__— DiffusionNFT keeps the defaultsupports_multi_update = False. Multi-update algorithms freeze their declared anchors:FlowGRPO/FlowDPPOpreparesde_logp;GRPOalways reuses the rollout log-prob, while DPPO/CPPO/DRPO do so underold_logp_source: rolloutand recompute it over the planned training micros underreplay.- FlowDPPO isn't fully on-policy under
rollout— it always replayssde_means(KL = 0) but keeps the engine'ssde_logp, so its ratio isn't pinned to 1. Usereplayto also pin the ratio. paramsmust reuse the rolloutguidance_scale/eta/shift— single-track recipes bindparams: ${sampling}; composed recipes bind the sub-block (e.g.${sampling.diffusion}). A mismatch silently skews log-probs.- DiffusionOPD's ODE recipes keep
sampling.etavanishing-but-nonzero (e.g.1e-6, sostage.replaystill emits log-probs) withadd_kl_coefficient=false. Never pair a near-zeroetawithadd_kl_coefficient=true— the KL divides by a transition std that scales witheta(the algorithm raises at init oneta == 0, but cannot judge "too small"). - AR
loss_agg_modeis one oftoken-mean|seq-mean-token-mean|seq-mean-token-sum-norm(unirl.types.loss_agg.LossAggMode; anything else raises at__init__).token-meanis the optimizer step's global token mean and requiressp_size: 1; theseq-mean-*modes average per-sequence values.loss_mask-inactive tokens never enter a denominator, and a fully-masked sequence still counts as one sequence that contributes 0. GSPO is sequence-level and takes noloss_agg_mode.UnifiedModelTrainStackweights micro-batches by sample share only, so itstoken-meanis not a global token mean. - AR
sampling_temperaturemust equal the rolloutsampling.temperature—ARStage.replayrescales logits by it (log_softmax(logits / T)) to match SGLang's distribution; when unset it silently falls back to theARSamplingParamsdefault, not the request Sample's actual temperature, biasing every ratio with no raise. Watchrollout_replay_logp_absdiff_mean— it should be ~0 on an on-policy step. - DiffusionNFT's
ref_deviation_coef > 0anchors to the LoRA-disabled base, not the EMA shadow — the shadow tracks the policy by construction, so anchoring to it would bound no drift. The reference is a thirdpredict_noise_at_stepper trained timestep, on top of the trainable and shadow ones; it runs underno_gradand needs no backward (~+24% train phase rather than +50%), and undertrain_timestep_mode: allit is paid once per timestep in the K-loop. That wall-clock number is not the whole cost — the penalty competes with the reward gradient, so at equal step count aref_deviation_coef > 0run settles at a lower proxy reward than aref_deviation_coef = 0one; budget steps for that rather than reading the trade off the timing alone.ref_deviation_coef=0returns aNonereference before any of that, so it stays bit-identical to a build without the term. ref_prediction_deviationis the raw mean-difference², not the σ-normalized KL — the metric is named for what it measures rather than forref_deviation_coef, which weighs it: the penalty is((new_pred - ref_pred)**2).mean(), the same formula as the neighbouringprediction_deviationwith the anchor swapped from the EMA shadow to the LoRA-disabled base, so the two share a scale and can be read side by side as drift-from-shadow against drift-from-base. DiffusionNFT trains on a freshly noisedxtrather than the rollout trajectory, so it has nostage.replaystep indices to hand_transition_sigma.segment.sigmasis present (train_timestep_mode: allrequires it) and so ist_batch, so a time weight is available if one is ever wanted; what is absent is the SDE transition std itself, because every NFT recipe runseta: 0.0and that std vanishes witheta— the same trap the DiffusionOPD bullet above raises on. That leaves theadd_kl_coefficient=falsevariant minus the/2, so the number is not comparable to FlowGRPO/FlowDPPO'skl_ref_mean, which carries_gaussian_kl_div's/(2σ²). Measuring on the prediction rather than the reconstructedx0drops thet²Jacobian ofxt - t*pred, spreading pressure uniformly over trained timesteps instead oft²-weighting it — the magnitude still moves witht(training lower timesteps raises it several-fold).adv_std_saturateis how many advantage σ map tor = 0or1— writeCfor the value andq = clamp(adv, ±C)/C ∈ [-1, 1]sor = 0.5 + q/2. Thentotalsplits exactly into(C/2)·mean(pos_loss + neg_loss)/βplus(C/2)·mean(q · (pos_loss − neg_loss))/β. Both halves carry the sameC/2, sototal = policy_loss * adv_std_saturateis a pure gain: it cancels the1/Cinsideqand leaves the objective's shape untouched, and the learning rate absorbs it. The/βis a gain as well — the raw NFT gradient scales linearly inβ(grad-norm/β is constant overβ = 0.05 … 1.0), so dividing by it makes the step β-independent. RaisingCshrinksE|q|(0.63 atC=1versus 0.16 atC=5) and the signal-to-symmetric ratio falls to 0.29x across that range. It is a first-class RL knob, not a safety clip.adv_std_saturate: 5.0de-contrasts ~3.4x against the paper's parameterization — DiffusionNFT (arXiv:2509.16117, Alg. 1) usesr = 0.5 + 0.5·clip(r_norm / Z_c, -1, 1)withZ_c"some normalizing factor, which could take the form of a global reward std", and its loss carries no outer scale. UniRL's advantages already arrive std-normalized (Part.compute_advantages(normalize= True)⇒(reward − group_mean)/(group_std + eps)), soadv_std_saturatedivides a z-score by another 5 andrspans only[0.066, 0.966]rather than saturating at 0 and 1. Consequence when porting coefficients: the policy term carries an overalladv_std_saturate/βgain that the upstream objective does not — 50x at the H3 recipe'sβ=0.1,adv_std_saturate=5— soref_deviation_coefis not on the same scale as verl-omni'sref_kl_coef. Check that factor before copying a value across. (verl-omni documents its own knob as a "prediction-space reference MSE regularizer", the same reading of the quantity this file takes above.)- The reference penalty is uninformative while the adapter delta is sub-ULP — both operands come
straight out of a bf16 forward, and standard LoRA init (
B=0) starts the delta at exactly zero. Below roughly 2 bf16 ULP (RMS delta ≲ 0.01 against O(1) predictions) the difference is mostly quantization noise: measured gradient-direction cosine against the fp32 answer is 0.52 at RMS 1e-3 and 0.97 at 1e-2. At the deviations these runs actually reach (0.008 → 0.057, i.e. 23 → 61 ULP) bf16 costs nothing measurable — 1.00x error, cosine 0.9999 — so the term is sound once the adapter has moved, and merely inert before that. Upcasting inside the penalty does not change this: the operands are already rounded when the forward returns them. DiffusionOPD'sfp32 before squaringis not the same situation — it upcasts scheduler-computedprev_sample_means, not raw network output.
Source:
unirl/algorithms/README.md— edit the README next to the code, then runnpm run sync:readmesfromdocs/.