Rollout
Rollout modes, engines, request planning, and response contracts.
Where it fits: the rollout step of the loop — rollout → reward → advantage → train → sync. In: a request
Samplefrom the trainer. Out: a filledSample. Full map:../README.md.
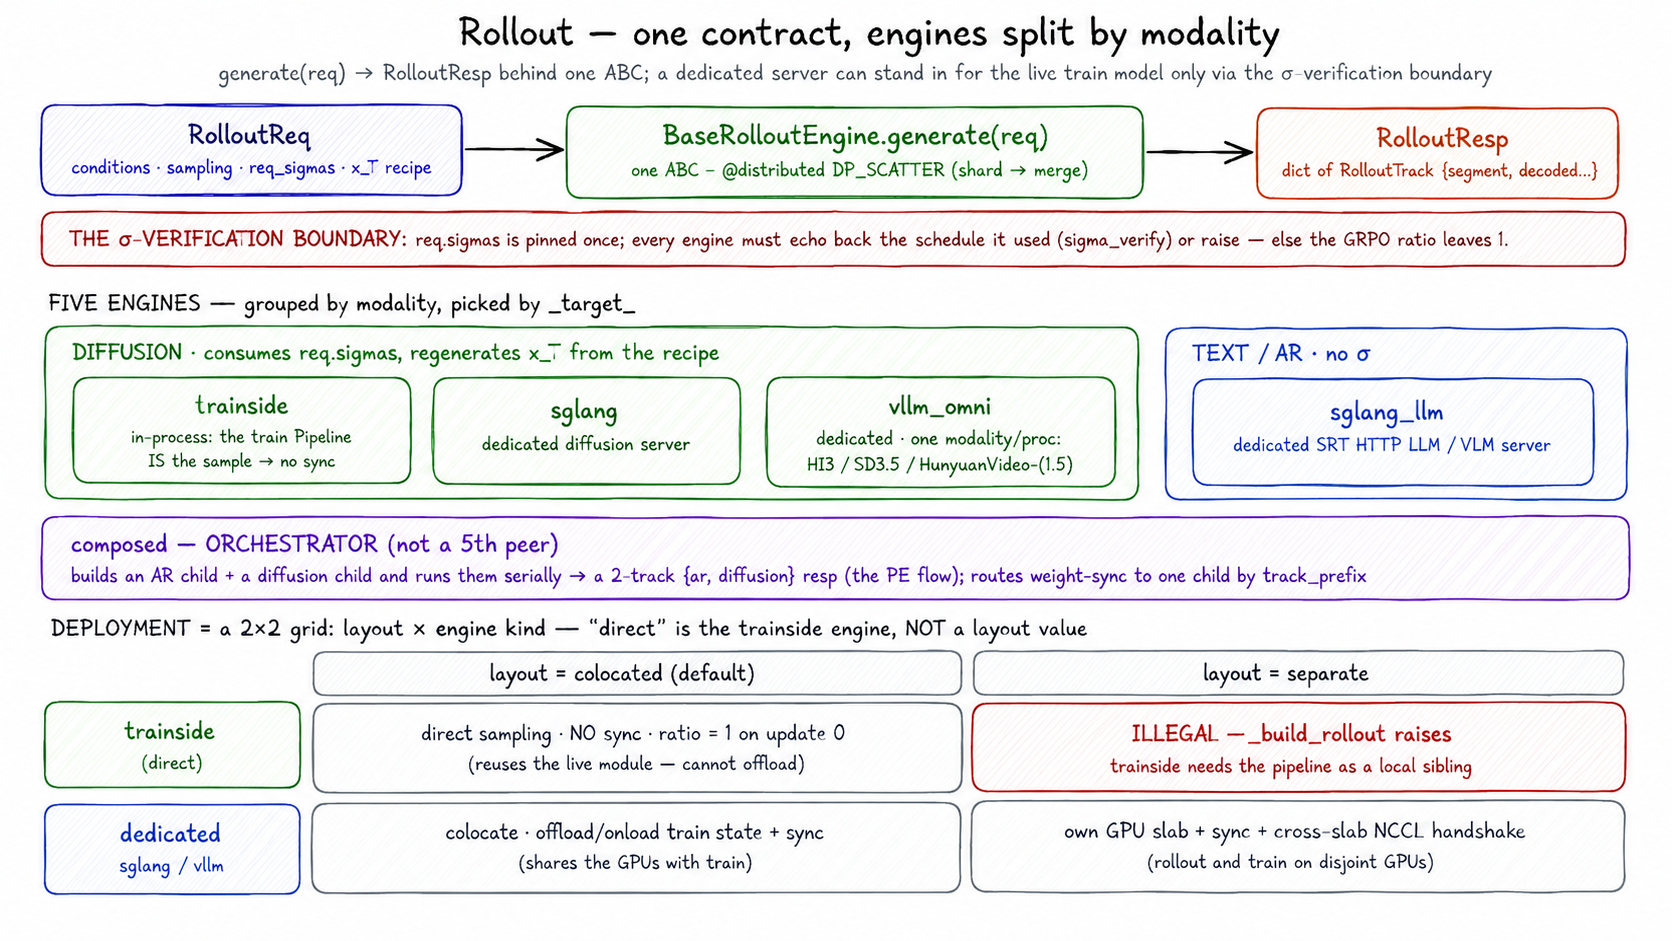
Every rollout engine fills one Sample. Agentic scheduling and group assembly live
in the driver-side rollout manager.
What it is
unirl.rollout owns the rollout engines — the box that fills a typed Sample by
running a model pipeline and the SDE step kernels. The agentic engine runs the
model/environment turns for one trajectory. It does not compute reward or loss.
Why it exists
The rollout can come from two unrelated codebases — the in-process training
Pipeline, or the SGLang fork sampling in its own subprocess. For on-policy RL they
must walk a numerically identical trajectory, because the trainer replays the
rollout to recompute log-probs and any drift silently pushes the GRPO ratio off 1.0.
So this module is a verification boundary, not just a backend-hiding shim: it
pins one σ schedule on the generated Part's sampling params and verifies what the
backend used (engine/sigma_verify.py). Each engine adapts its backend wire format
into canonical Part fields, so a dedicated server swaps in for the training model
without the loop noticing, and a mismatch crashes loudly instead of training on a
wrong objective.
How it works
- One generation interface.
BaseRolloutEngine(engine/base.py) is aRemotewhose concrete engines implement synchronousgenerate(sample); each returns oneSample. Batch engines dispatchgeneratewithDP_SCATTER. Agenticgenerateis undecorated because the driver manager addresses one engine slot per trajectory; Ray actor concurrency lets the inner backend batch concurrent calls. - The typed boundary (
../types/). ASampleis an ordered chain ofParts. Each Part carries lineage ids, a rawprimitive, an encodedsegment, replay conditions, sampling params (including the σ schedule), and optional decoded media. Single-stage flows fill one generated Part; composed PE fills its chained AR and diffusion Parts. - The engines.
trainside(in-process — the train actor's pipeline is the sampler),sglang_diffusion(dedicated diffusion),sglang(dedicated AR),vllm_omni(dedicated; BAGEL / HI3 / SD3 / HunyuanVideo),fastvideo(dedicated accelerated video sampling), andcomposed(chains an AR child + a diffusion child for prompt enhancement) are the six single-turn engines.agenticwraps one of them with an environment to produce multi-turn trajectories. Each diffusion engine consumes the Part's pinned sigmas verbatim and reads the same driver-authoredNoiseRecipe(../types/noise_recipe.py), but realizes it differently:trainside,sglang_diffusionandvllm_omniresolve the recipe to anx_Ttensor, so those three start a rollout from bit-identical noise;fastvideocannot accept a tensor and instead derives per-sample seeds from the recipe's noise-group ids, so its noise matches only in grouping, not bit-for-bit.forward_batch_sizebounds peak memory by slicing the Sample and concatenating the results. - Deployment modes: direct sampling — the trainside engine, no
sync:, the ratio is 1 on the first update; separate — a dedicated engine on its own GPUs plus async:block; colocate — a dedicated engine sharing GPUs with train, plus offload/onload andsync:. - Driver-side scheduling. One
manager.RolloutManagerserves batch and agentic trainers. Its progress thread dispatches bounded work and observes readiness; trainer-thread collection resolves results, assembles agentic siblings, and applies the configured filter. Async batch trainers own training progress and publication cadence; the manager owns the published rollout version and preserves completed generations as FIFO batch chunks.AgenticTrainercollects one complete barrier batch per step. Async AR refills the same manager immediately after collection, so its existing progress thread overlaps the next generation with scoring and training. Publication and durable boundaries still quiesce that single manager before proceeding.
Extending it: a new single-turn engine adds engine/<name>/config.py (a
BaseEngineConfig whose make_engine(**deps) lazily imports and builds it) and
engine/<name>/engine.py (subclass BaseRolloutEngine, implement
synchronous generation over the whole-Sample contract — thread-safe for
concurrent callers if it should serve as an agentic inner, else serialized
internally — and dispatch generate with DP_SCATTER). A dedicated engine also
implements its weight-receive method and a matching sync: handler in
../distributed/weight_sync.
Engine anatomy, and adding a model to an existing engine
Engine dirs use two layouts. The compact engines (trainside, fastvideo,
composed, agentic) contain config.py + engine.py. Server-backed engines
(sglang, sglang_diffusion, vllm_omni) also carry adapters/
(per-family/modality wire-format translation), backends/ (server process
management), utils/, weight_sync.py, and a
runtime-patch dir for the pinned upstream (sglang_diffusion/_patches/,
vllm_omni/patches/). vllm_omni additionally carries worker-subprocess code
(pipelines/, worker/) and deployment configs (deploy_configs/).
Model onboarding is per-engine, and the adapter file is usually not the whole change surface:
sglang(AR/VLM): onboarding is normally config-only: text models use thetextadapter, whileimage_tokenselectsvlm. Add and register a new adapter only for a genuinely new wire shape, extendingTextLMAdapterorVLMAdapterand importing it inadapters/__init__.py.sglang_diffusion: addadapters/<family>.pyextendingImageAdapterorVideoAdapter, register it bymodel_family, and import it inadapters/__init__.py. New condition fields that cross the wire also need an entry in_COND_FIELDSand either_POS_MAP/_NEG_MAPor an explicit copy branch in_copy_conditions; add_patches/hijack.pywiring only when the model needs a new upstream patch.vllm_omni: add anadapters/<family>.pybinder (keyed by modality), register it, import it inadapters/__init__.py, and add the appropriate boot YAML underdeploy_configs/. DiT families additionally need a worker-sidepipelines/<model>/pipeline.py; if the AR/DiT worker needs new behavior, add aworker/extension orpatches/compat_<model>.py.
SGLang AR knobs
The 4B dense Qwen3 AR recipes (examples/ar/qwen3_*_sglang*.yaml) share a
colocate full-FT engine_kwargs baseline. Async/separate, larger-model,
MoE, and LoRA recipes deliberately deviate as described below and in their
inline comments. Typed SGLangEngineConfig fields overlay engine_kwargs;
reserved ports always win. Keys that are not live SGLang ServerArgs fields
warn at boot (or raise if UNIRL_SGLANG_STRICT_SERVER_ARGS=1) — see
engine/README.md.
4B dense colocate full-FT baseline (FSDP train shard time-shares the GPU; TensorWeightSync):
| Knob | Preset | Why |
|---|---|---|
mem_fraction_static | 0.3 | Lower SRT KV reservation so FSDP can all-gather full dense weights. server_intent() defaults to 0.88 if omitted — too high for colocate. |
enable_lora | false | TensorWeightSync pushes full dense weights; a LoRA pool would be the wrong receive path. |
cuda_graph_max_bs_decode | 16 | CUDA graph stays on (disable_cuda_graph: false); SGLang otherwise auto-tunes the capture cap from GPU memory and TP size, often reserving much larger buffers that fight the weight push. |
skip_server_warmup | true | Skip SRT startup warmup on the 4B colocate path; this knob does not control wake_up(). |
attention_backend | triton | Matches the in-tree 4B full-FT recipes. |
Larger / MoE colocate: memory and graph settings are recipe-specific
(mem_fraction_static ranges from 0.15 to 0.5; graph caps include 64 and
128, and one VLM MoE recipe disables graphs). Several MoE/CPPO recipes set the
typed skip_server_warmup: false, which wins over engine_kwargs, so startup
warmup runs. The VLM MoE geo3k recipe also leaves attention_backend to
SGLang's platform selection.
Async / separate (*_sglang_async.yaml): the engine owns the GPU (no colocated
FSDP shard). Raise mem_fraction_static to 0.8 and leave the other 4B baseline
keys as-is; keep headroom for NCCL weight-receive buffers. Sync is
NCCLWeightSync.
LoRA colocate (*_sglang_lora.yaml): enable_lora: true plus the SGLang LoRA
pool knobs. This is the exception to the full-FT enable_lora: false receive path
(LocalLoraWeightSync instead of TensorWeightSync). Memory numbers are recipe-specific.
Reserved ports: SGLangPorts.reserve() selects candidate HTTP port and
nccl_port values by binding temporary sockets on the engine's node, then
closes those sockets so SGLang can bind (the usual bind-to-zero TOCTOU gap
remains). Do not set port / nccl_port in engine_kwargs — the selected
values overwrite them. The retired 35535 cap is unnecessary on 0.5.19:
SGLang derives grpc_port = port + 10000 only when gRPC mode is explicitly
enabled, which UniRL's rollout backend does not do.
Gotchas
- SGLang diffusion tensor LoRA accepts standard PEFT LoRA only. A global
lora_alphais supported; rsLoRA, DoRA, per-layer alpha patterns, and PEFT auxiliary features fail closed.use_lora=trueselects adapter-only sync for the engine lifetime. Full-weight sync requiresuse_lora=false; a trainer using LoRA must merge the adapter before pushing those full weights. - A colocated SGLang engine needs
enable_memory_saver. Without it SGLang installs a no-opTorchMemorySaverAdapter:release_memory_occupationreports success and frees nothing. Addenable_weights_cpu_backup: trueto move weights to host across the sleep.AgenticTrainerrejects a colocated engine without the flag;ARTrainerwarns. - Size
mem_fraction_staticfrom the wake peak, not the rollout peak. InAgenticTrainerthe engine wakes beforebackend.offload()releases the train state, andtorch_memory_saver'sresume()cannot reuse blocks held by torch's caching allocator. Take the peak over several rollouts; turn counts vary run to run. - KV offload (HiCache, Mooncake) only helps above the radix-cache knee. With
R = concurrency × per-trajectory context / KV pool, prefix reuse stays flat up toR ≈ 1and drops beyond it; below that a host tier has nothing to recover. Raisingmem_fraction_staticlowersR, so re-measure it before adding a tier. - Never recompute σ inside an engine — the generated Part's pinned sigmas are
the single source of truth;
engine/sigma_verify.pychecks the backend echo (it guards the GRPO log-prob ratio). - Batch
generatemust dispatchDP_SCATTER. Agentic is the intentional exception: its undecorated method is reached through oneHandle.slot(...). - Direct sampling forbids a
sync:block; dedicated requires one. The trainside engine also can't live on alayout: separateslab —_build_rolloutraises. - Quiesce before weight sync / eval / checkpoint on async paths —
RolloutManager.quiesce()pauses dispatch, drains batch work, and cooperatively suspends agentic trajectories at turn boundaries.sync_weights()rejects queued or in-flight work, pushes weights, and publishes the optimizer-updateoutput_version; immutable buffered groups keep their original provenance and remain subject to the configured filter. Eval/checkpoint admission still requires an empty manager. Launch and scoring order remains trainer policy. - A resolve/route failure poisons the
RolloutManager— samples may already be lost, so every later call (includingempty/counts) re-raises the original error rather than reporting clean state; onlyclose()stays safe. - Reward/advantage methods are not engine code —
Part.compute_advantagesandSample.propagate_rewardsare called by the trainer after scoring. An engine fills generation fields such assegment,conditions,primitive, andmedia_preview; rewards arrive later fromRewardService.
Source:
unirl/rollout/README.md— edit the README next to the code, then runnpm run sync:readmesfromdocs/.